
- Starting price
- $0.008per 1M input tokens
- Website
- fireworks.ai
About Fireworks AI
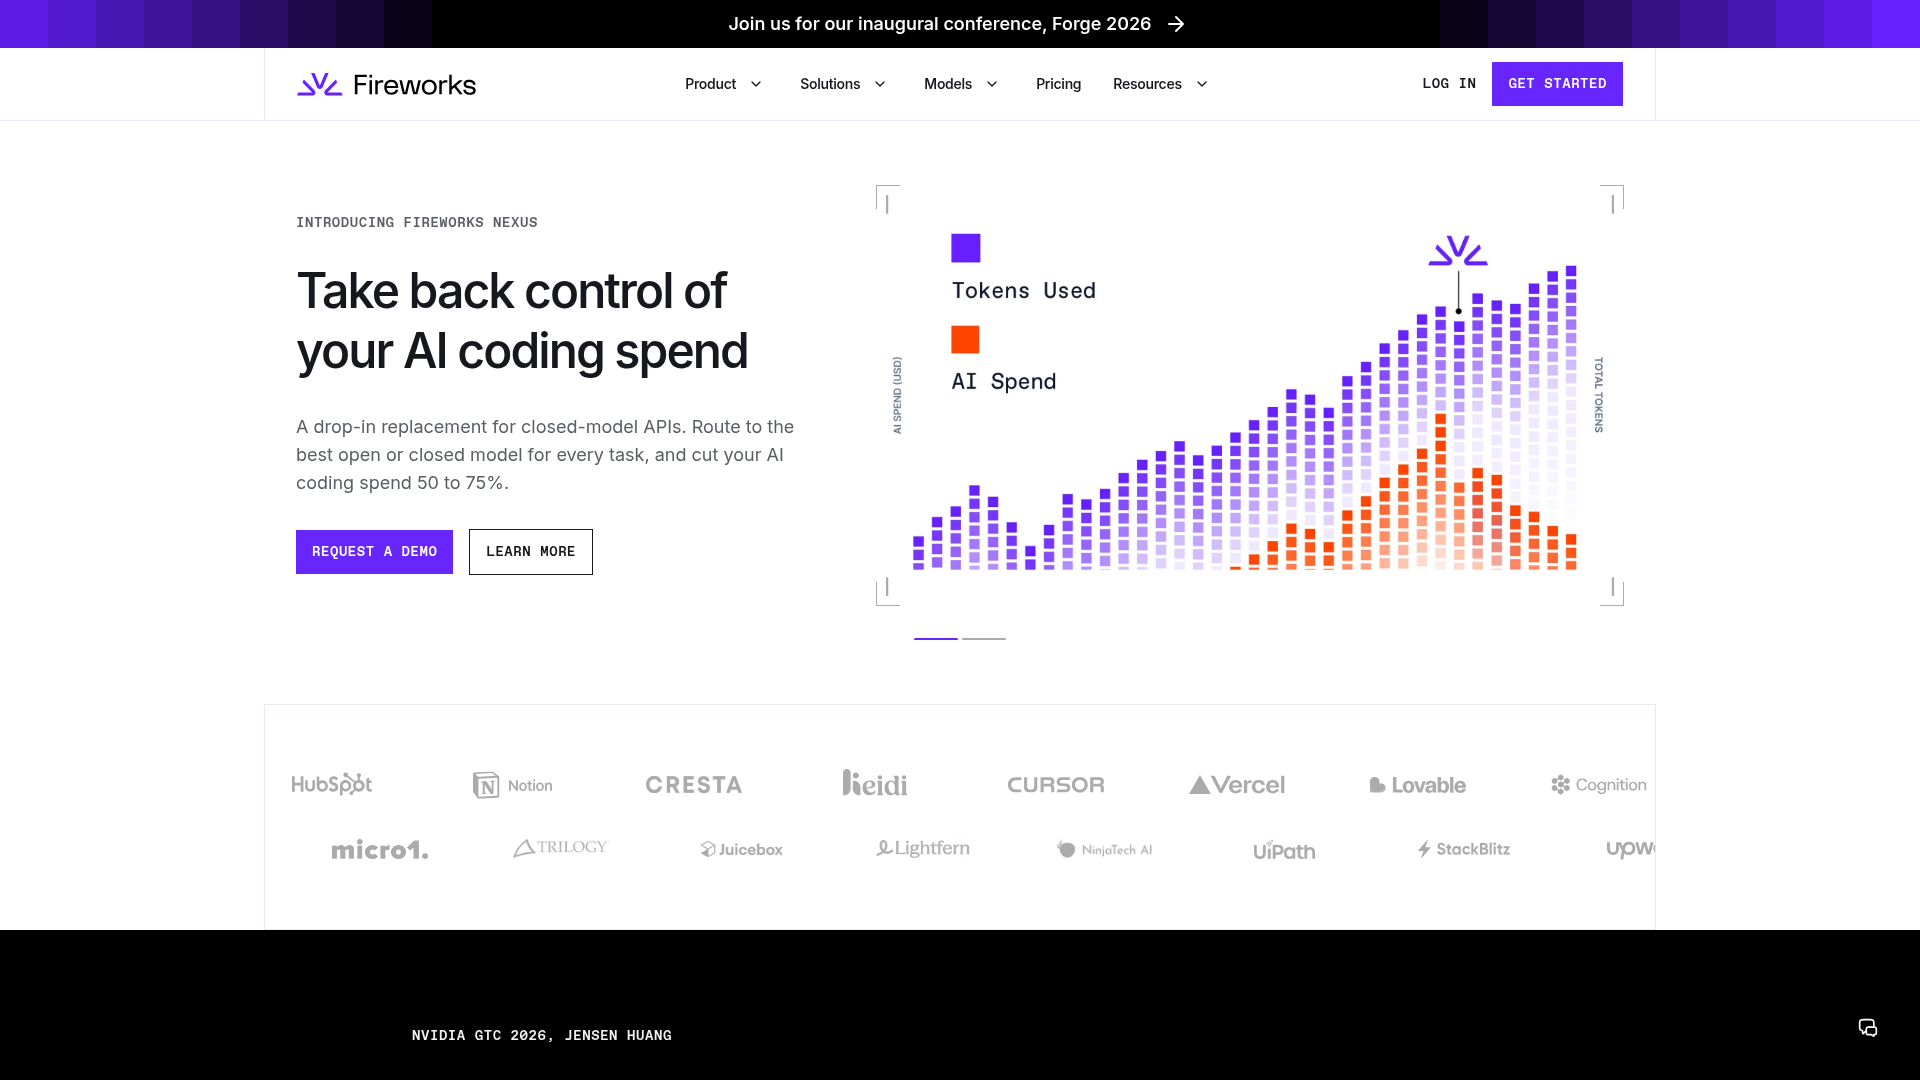
Fireworks AI is a drop-in replacement for closed-model APIs that routes to the best open or closed model for each task. It serves developers and ML teams who want to own their AI stack and reduce spending while preserving performance.
Key Features
Engineers juggle multiple models and want to avoid vendor lock while controlling costs. Nexus lets you route tasks to the best open or closed model and swap on the fly to balance cost and accuracy:
Model Routing Engine
Routes each task to the best open or closed model, with dynamic re-routing as needs change.
Drop-in API Replacement
Works as a direct substitute for existing closed-model APIs, so you can switch without rewriting client code.
Cost Reduction
Aims for a 50–75% cut in AI coding spend by steering queries to cheaper models when suitable.
Specialized Intelligence via SoTA Training & Inference
Transforms open models into your tailored capabilities through state-of-the-art training and inference.
Summary
Best for ML/AI engineers, platform teams embedding AI in apps, and data science groups aiming to optimize model usage.
Pricing
View pricingPlans and prices as listed on fireworks.ai as of Sep 24, 2026.
Embeddings (up to 150M)
$0.008 / per 1M input tokens
- Base model parameter count: up to 150M
- Pricing per input tokens
Embeddings (150M - 350M)
$0.016 / per 1M input tokens
- Base model parameter count: 150M - 350M
- Pricing per input tokens
Embeddings (Qwen3 8B)
$0.1 / per 1M input tokens
- Base model: Qwen3 8B
- Pricing per input tokens
On-Demand Deployments (H100 80 GB GPU)
$0.134 / per minute
- Price per hour: $8.00
On-Demand Deployments (H200 141 GB GPU)
$0.134 / per minute
- Price per hour: $8.00
On-Demand Deployments (B200 180 GB GPU)
$0.217 / per minute
- Price per hour: $13.00
On-Demand Deployments (B300 288 GB GPU)
$0.250 / per minute
- Price per hour: $15.00
On-Demand Deployments (GB300 288 GB GPU)
$0.334 / per minute
- Price per hour: $20.00
Managed Training (Models up to 16B)
$0.50 / per 1M training tokens
- Supervised fine tuning
- Fine tuning pricing
Serverless Training API (DeepSeek V4 Flash 0731)
$1.74 / per 1M
- Context: 262K
- Prefill
- Cached Prefill
- Sample
- Train
Serverless Training API (Qwen 3.8 27B)
$1.86 / per 1M
- Context: 128K
- Prefill
- Cached Prefill
- Sample
- Train
Serverless Training API (Muse Glimmer 30B)
$1.96 / per 1M
- Context: 128K
- Prefill
- Cached Prefill
- Sample
- Train
Managed Training (Models 16.1B - 80B)
$3.00 / per 1M training tokens
- Supervised fine tuning
- Fine tuning pricing
Serverless Training API (GLM 5.3)
$4.86 / per 1M
- Context: 262K
- Prefill
- Cached Prefill
- Sample
- Train
Managed Training (Models 80B - 300B)
$6.00 / per 1M training tokens
- Supervised fine tuning
- Fine tuning pricing
Managed Training (Models >300B)
$10.00 / per 1M training tokens
- Supervised fine tuning
- Fine tuning pricing
Serverless Training API (Kimi K3)
$10.87 / per 1M
- Context: 192K
- Prefill
- Cached Prefill
- Sample
- Train
More in Inference
See all →
Inference Platform: Deploy AI models in production

The world's fastest AI inference on the biggest wafer chip

Machine Learning Models and Infrastructure

High-performance AI infrastructure

The Ultimate AI Cloud

Model Libraries & GPU Cloud - Deploy, Scale & Innovate
Fireworks AI Reviews
No reviews yet. Used Fireworks AI? Be the first to review it.